Mar. 16, 2019
用Python做了个Websocket的服务端,虽然知道相关的库应该早就有了,但是还是想自己做出来。
当然也参考了不少网上的教程,琢磨了好久的Websocket协议的格式。
内含一个WebsocketServer类,可以实现握手、建立连接、心跳(ping)、传输数据、上下文管理器。可以接收任意类型的数据,发送字符串(稍微改一下也可以发送二进制数据),支持数据分片(传输和发送都可以)。
More...
Feb. 10, 2019
后端的最后一部分。
-
- import json
- import re
-
-
- class Lyric2Book:
- support_format = ['txt', 'html']
- support_ts = ['parallel', 'chunk']
- html_template = """
- <section>
- <h2 class='header'>%(header)s</h2>
- <div class='info'>
- <div class='album'>%(album)s</div>
- <div class='artists'>%(artists)s</div>
- </div>
- <div class='content'>
- %(lyrics)s
- </div>
- </section>
- """
- html_frame = """<!DOCTYPE html>
- <html lang="zh-cn">
- <head>
- <meta charset="utf-8"/>
- <meta name="viewport" content="width=device-width, initial-scale=1" />
- <meta name="referrer" content="never" />
- <title>%s</title>
- </head>
- <body>
- %s
- </body>
- </html>
- """
- lyrics_template = "<div class='content-%(ver)d' >%(content)s</div>"
- txt_template = "%(header)s\n专辑:%(album)s\n作者:%(artists)s\n\n%(lyrics)s\n\n"
- txt_frame = "%s\n\n%s"
-
- def __init__(self, file_format='html', title='Lyrics', typesetting='parallel'):
- self.title = title
- if file_format in Lyric2Book.support_format:
- self.format = file_format
- else:
- raise Exception('Unsupported format: %s.' % file_format)
- self.res = ""
- self.data = ""
- if typesetting in Lyric2Book.support_ts:
- self.ts = typesetting
- else:
- raise Exception('Unsupported typesetting: %s' % typesetting)
-
- def chunk(self, lyrics):
- predlyric = []
-
- for item in lyrics:
- lines = []
- if item is not None:
-
- for line in item.split('\n'):
- line = re.sub('\(\d+,\d+\)', '', line)
- time_tag = ''.join(re.findall('\[.*?\]', line))
- line = [time_tag, line.strip(time_tag)]
- lines.append(line)
- predlyric.append(lines)
- output_section = ''
- if self.format == 'html':
- i = 1
- for item in predlyric:
- output_section += "<div class='content-%d'>\n" % i
- i += 1
- for line in item:
- output_section += "<p><span class='timetag'>%s</span>%s</p> \n" % (re.sub('[\[\]]', '-', line[0]), line[1])
- output_section += "</div>"
- elif self.format == 'txt':
- for item in predlyric:
- output_section += ""
- for line in item:
- format_tag = '-%s- ' % re.sub('[\[\]]', '-', line[0]) if line[0] else ''
- output_section += format_tag + line[1] + '\n'
- return output_section
-
- def parallel(self, lyrics):
- unpredlyric = []
- for item in lyrics:
- lines = {}
- if item is not None:
- for line in item.split('\n'):
- line = re.sub('\(\d+,\d+\)', '', line)
- time_tag = ''.join(re.findall('\[.*?\]', line))
- lines[time_tag] = line.strip(time_tag)
- unpredlyric.append(lines)
- predlyric = []
- for group_tag in list(unpredlyric[0].keys()):
- predlyric += [[group_tag] + [i.get(group_tag, unpredlyric[0][group_tag]) for i in unpredlyric]]
- dparallels = predlyric
- output_section = ''
- if self.format == 'html':
- for item in dparallels:
- output_section += "<div class='content'>\n"
- dtimetag = item[0]
- dcontent = item[1::]
- item_div = "<div class='timetag'>\n<p>{timetag}</p>\n</div>\n<div class='single-lyric'>\n{content}</div>\n"
- output_spar = ''.join("<p class='ver-%d'>%s</p>\n" % (c[0], c[1]) for c in enumerate(dcontent, 1))
- output_section += item_div.format(timetag=re.sub('[\[\]]', ' - ', dtimetag), content=output_spar) + '</div>'
- elif self.format == 'txt':
- for item in dparallels:
- dtimetag = item[0]
- dcontent = item[1::]
- item_div = "{timetag}\n{content}\n"
- output_spar = ''.join("%s\n" % c[1] for c in enumerate(dcontent))
- output_section += item_div.format(timetag=re.sub('[\[\]]', ' - ', dtimetag), content=output_spar)
- return output_section
-
- def doconv(self, sections):
- last_album = ''
- output = ''
- for item in sections:
- header = item['name']
- album = item['album']
- artists = ','.join(item['artists'])
- a = item['lyric']
- if a is not None:
- ly_res = {}
- lyrics = [a['0'], a['1'], a['2']]
- if self.ts == 'parallel':
- ly_res = self.parallel(lyrics)
- elif self.ts == 'chunk':
- ly_res = self.chunk(lyrics)
- if self.format == 'html':
- if last_album != album:
- last_album = album
- output += '<h1>%s</h1>' % album
- output += Lyric2Book.html_template % {'header': header, 'album': album, 'artists': artists, 'lyrics': ly_res}
- elif self.format == 'txt':
- if last_album != album:
- last_album = album
- output += album + '\n\n'
- output += Lyric2Book.txt_template % {'header': header, 'album': album, 'artists': artists, 'lyrics': ly_res}
- self.res = output
-
- def output(self):
- filename = self.title + '.' + self.format
- with open(filename, 'w+', encoding='utf-8') as f:
- res = self.res
- if self.format == 'html':
- res = Lyric2Book.html_frame % (self.title, res)
- elif self.format == 'txt':
- res = Lyric2Book.txt_frame % (self.title, res)
- f.write(res)
-
-
- if __name__ == '__main__':
- with open('bbc.txt', 'r', encoding='utf-8') as file:
- t = Lyric2Book(file_format='thjxt', title='BBC Documentary', typesetting='parallel')
- content = json.loads(file.read())
- t.doconv(content['result'])
- t.output()
Feb. 6, 2019
2019年的春节只有5天,二十八放假,初三上课。
放假前几分钟,我在想我能够做什么做什么,把计划中的事,未做完的事,未计划的事统统完成,大部分都是课外的事。
我确实完成了一些,但有些我却总也走不下去。歌词工具从十月份开始有想法,十一月份真正开始,到现在有三四个月了。借着这个想法我才真正熟悉了Python,后台逻辑其实一个月以前就结束了,一些改进的想法也决定搁置,没有再重构;前端最关键的部分也测试证明可行,然后我就不走了。
More...
Nov. 11, 2018
最近想把网易云音乐中的英语听力下载到播放器中,方便随时听。但是只下载音频的话就少了些什么,最好连听力的歌词也下载进去。于是乎写了个小工具,可以批量下载歌单或者专辑中的音乐的歌词,可以省很多时间。
netease-lyric.py
-
- import requests
- from bs4 import BeautifulSoup
- import json
- import re,os
- from spider import *
- def get_html(url):
- headers = {
- 'User-Agent':'Mozilla/5.0 (Windows NT 10.0; Win64; x64) AppleWebKit/537.36 (KHTML, like Gecko) Chrome/70.0.3538.77 Safari/537.36',
- 'Referer':'http://music.163.com',
- 'Host':'music.163.com'
- }
- try:
- response = requests.get(url,headers=headers)
- html = response.text
- return html
- except:
- print('request error')
- pass
-
- def get_lyric(song_id):
- url = 'http://music.163.com/api/song/lyric?' + 'id=' + str(song_id) + '&lv=1&kv=1&tv=-1'
- html = get_html(url)
- json_obj = json.loads(html)
- print(json_obj)
- lyric = json_obj['lrc']['lyric']
- return lyric
-
- def get_details(song_id):
- url = 'http://music.163.com/api/song/detail/?' + 'id=' + str(song_id) + '&ids=%5B' + str(song_id) + '%5D'
- html = get_html(url)
- print(html)
- json_obj = json.loads(html)
- song_name = json_obj['songs'][0]['name']
- song_artist = json_obj['songs'][0]['artists'][0]['name']
- return song_name,song_artist
-
- def output_file(song_id):
- song_name,song_artist = get_details(song_id)
- lyric = get_lyric(song_id)
- file_name = song_name + ' - ' + song_artist + '.lrc'
-
- file_name = file_name.replace('/','/')
- file = open(file_name,"w+",encoding="utf-8")
- file.writelines(lyric)
- file.close()
-
- url = "https://music.163.com/album?id=2817001"
- id_list = get_songlist(url)
- print(id_list)
-
- for iterm in id_list:
- output_file(iterm)
抓取歌单中的歌曲信息,获得id
spider.py
More...
Oct. 20, 2018
首先恭喜IG击败LCK头号种子KT,打入四强。
然后,让我们用最饱满的热情恭喜夺冠热门RNG喜提八强,提前回家。
怎么说呢,IG赢KT我的确想到过,但是没有想到IG怎么做才能打赢KT。我曾经想过如果IG能赢KT我要吹IG一辈子,因为今天不仅是S8的四分之一决赛日,也是我的18岁生日。那么现在就是我兑现诺言的时候了。
More...
Oct. 3, 2018
最近遇到了几首很好听的歌曲,为了方便,就打算将歌词编辑出来放到Kindle。大概的步骤是先在Word上排好。然后用Calibre转换成Kindle能识别的格式。最初效果很好,抱着Kindle唱歌感觉非常有B格。后来同学也让我查几首歌的歌词放上去,这样歌曲从原来的两三首增加到八首,这样一页一页的翻找就比较费力,于是乎我用Calibre编辑功能为它自动生成了目录,一切和想象中的一样顺利,但是选择目录时却遇到了一件尴尬的事:
More...
Oct. 1, 2018
秋凉猛袭,世界似乎在一夜之间变得萧索了,早上出门,迎面而来的是阵阵凉意。夏和秋的分界线变得格外清晰,只是一个晚上,寒流就横扫大地,劫掠走夏天的最后几丝热量,然后君临天下,好不壮阔。接下来,便是阴雨、落叶和阴雨。
More...
Aug. 24, 2018
我在忙最后一件事,这几天一直在采购东西,为这最后一件事。
一块2.5寸机械硬盘,已经无力回天,但是控制电路和电机都能用的硬盘。把它拆开,可以看到光洁的盘片,通上电还能盘片还能转动,磁头也能动。浓浓的机械的美感。
More...
Aug. 9, 2018
话说最近真是干啥啥不行。
先说背景
手机被收了,只能用树莓派听歌,不过我的派并没有配屏幕……所以最初的方法是:打开电脑->连上VNC->打开树莓派的浏览器访问网易云,虽然能听,但是切歌、调音量都得通过电脑调,很麻烦,而且开着Chromium树莓派发热恐怖。
More...
Jul. 27, 2018
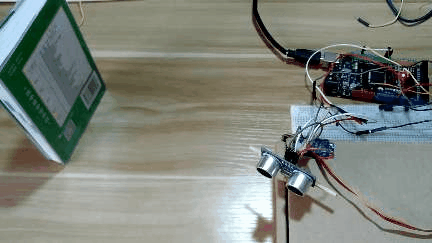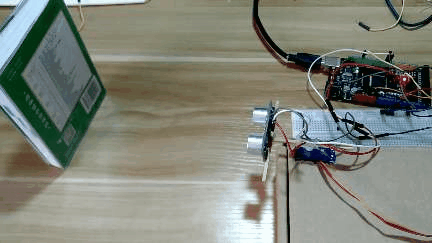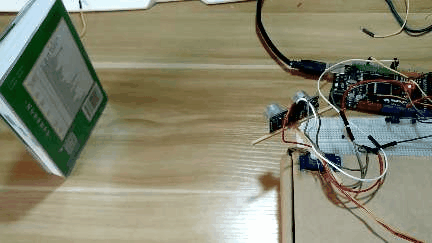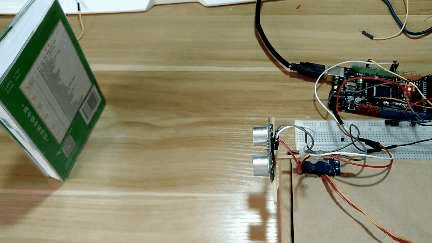
关于这个用Arduino做超声波雷达的项目,我在Create Arduino上见过很多次,这里就自己做出来试试。
主要原理是利用超声波测距,然后使用Processing在屏幕上绘制出雷达图,总体比较简单。
成品
More...
